Part 4 of 4
GradientMail
GradientMail implements the exchange of Decoupled DiLoCo around existing training loops. PyTorch or MLX handles the forward pass, autodiff, and inner optimizer; GradientMail handles fragment exchange and shared updates.
Machines communicate through a mailbox, such as an S3-compatible bucket. They need access to that store, but do not need direct connections to each other. The store holds tensor payloads and coordination records; computations run on the training machines.
Every node also runs the syncer runtime. One node is elected through the mailbox to close rounds. If it fails, another can recover the committed state and take over. This hosts the syncer role on a learner instead of requiring the dedicated central synchronizer described in the paper.
What happens in one round
- A learner trains locally from a committed fragment, its anchor.
- When a contribution is due, it publishes
anchor - local_parametersfor that fragment, together with the anchor version and its step and sample counts. - The elected syncer accepts contributions based on the current fragment version and rejects stale or incompatible ones. It waits for quorum, or for every live learner to report with at least one accepted contribution, then allows an adaptive grace window for additional reports.
- It merges the accepted deltas, applies the outer optimizer, and publishes the new fragment and outer optimizer state. A create-once round record commits the result.
- Learners fetch the result in the background and align with it between local training steps.
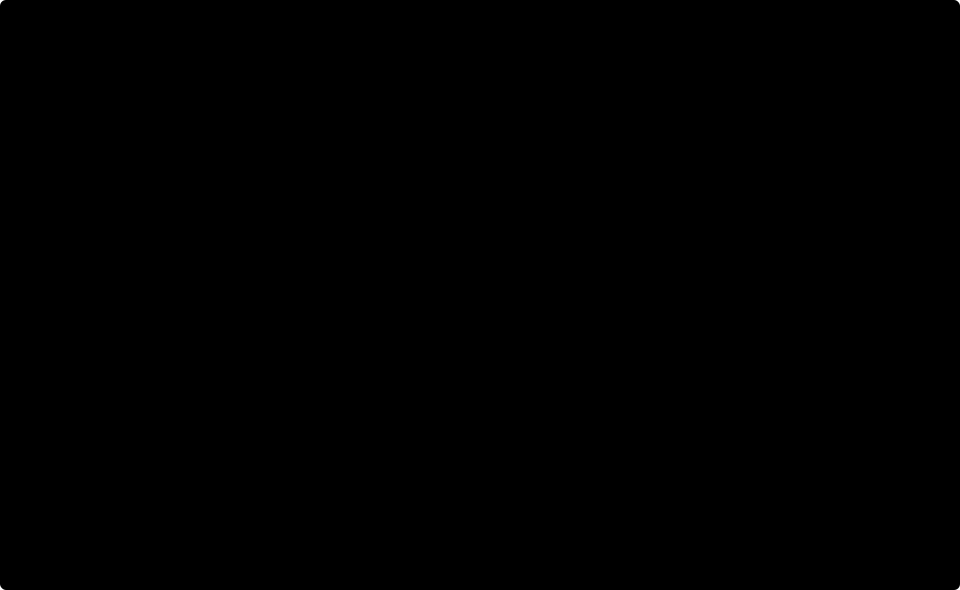
The default merge weights each contribution by samples² / steps since the
learner last aligned with that fragment. It uses radial-directional averaging
(RDA) for most tensors: average the delta lengths and directions separately,
then rescale the mean direction to the mean length. Parameters whose names
contain embed use a weighted mean instead.
The outer optimizer uses Nesterov momentum.
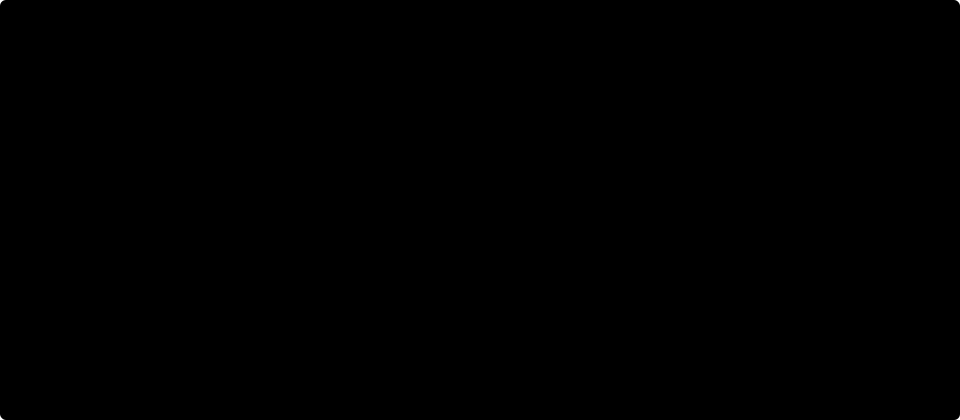
Tensor payloads use Safetensors, with JSON records for metadata. Version checks prevent applying a delta against the wrong anchor. Committed outer state supports syncer recovery; inner optimizer state stays local and must be checkpointed separately.
Connecting a training loop
Install the package with the extras for the mailbox and the framework:
uv add "gradientmail[s3,torch]"
The integration has this shape; train_step is the application’s existing
forward pass, backward pass, and optimizer update:
import gradientmail as gm

with gm.Session(
    model,
    algorithm=gm.DiLoCo(sync_every=100, fragments=8),
    mailbox=gm.S3Mailbox(bucket="my-training", prefix="runs/example"),
) as session:
    for batch in dataloader:
        loss = train_step(model, optimizer, batch)
        session.step(samples=len(batch))
Run a learner on each machine with the same mailbox location, algorithm configuration, and compatible model definitions. Compatibility includes parameter names, shapes, dtypes, and their meaning in the model. Sharing a file format alone does not make different model implementations interchangeable. The first learner initializes the run; later learners load its committed weights.
Here, sync_every=100 sets the nominal interval for each fragment, with up to
eight fragments staggered across that interval. It does not mean that all eight
fragments are exchanged together every 100 steps. Actual contributions depend
on learner progress and round readiness.
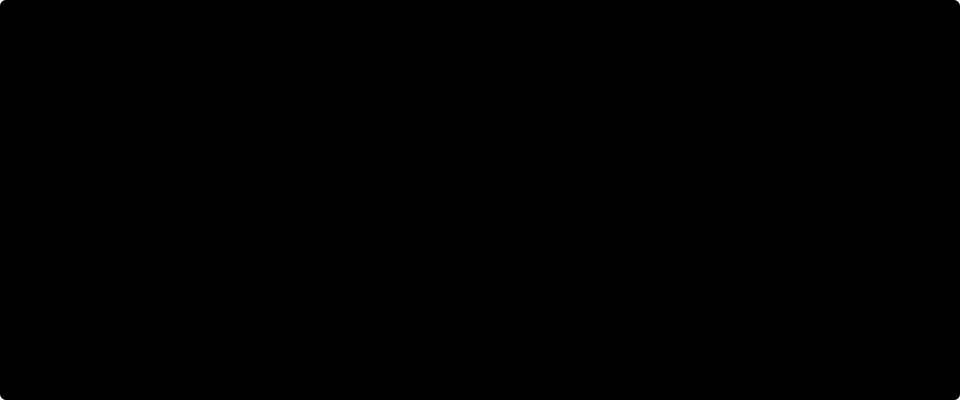
Call session.step after each local optimizer update. Report the number of
examples for example-based training, or tokens for token-based training;
len(batch) is appropriate only when it measures that count. Learners in the
same run must use the same unit.
Choosing the tradeoff
By default, training continues during exchange. Aligning with a committed
fragment replaces that fragment’s local parameters, including updates made while
its contribution was in flight. gm.DiLoCo(..., overlap_steps=0) makes every
learner wait for the commit instead; a larger bound lets it train that many
steps past a publish first, and mixing blends what it trained meanwhile with
the commit instead of replacing it.
Closing the session waits for the learner’s rounds in flight to commit and sets
the model to the newest committed parameters. Steps trained since a fragment’s
last contribution are dropped, as in the DiLoCo papers. With
gm.DiLoCo(..., flush_on_close=True), the learner publishes them instead, and
a round made only of these final contributions commits them without the outer
momentum.
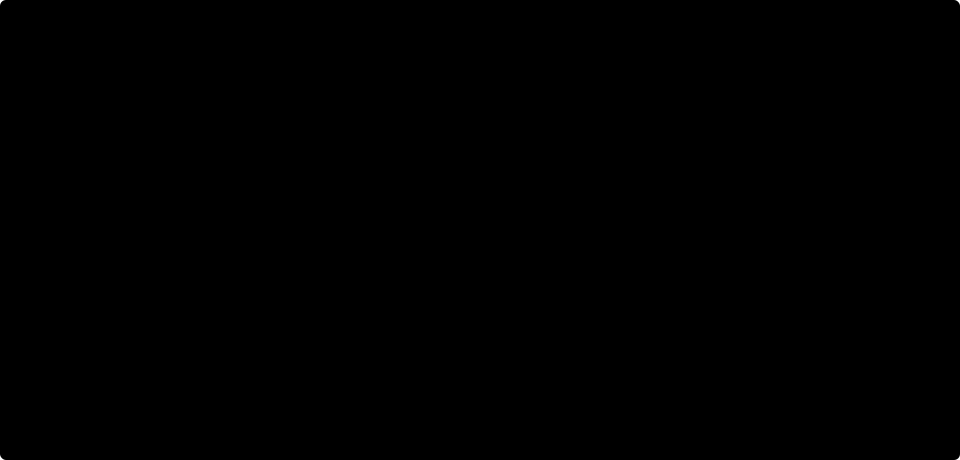
quorum_size defaults to 1, allowing a round to proceed with one contribution.
A larger quorum seeks more contributions before merging, at the cost of more
waiting; live membership also affects when a round may close. A crashed learner
stops counting as live after its lease expires.
This design targets independent machines, uneven hardware, and networks where per-step gradient exchange is expensive. DDP remains a suitable choice for tightly connected accelerators. GradientMail still requires enough memory for each learner’s model and optimizer, enough bandwidth for fragment exchange, and validation that the chosen synchronization settings train the model well.
Previous: DiLoCo and its variants